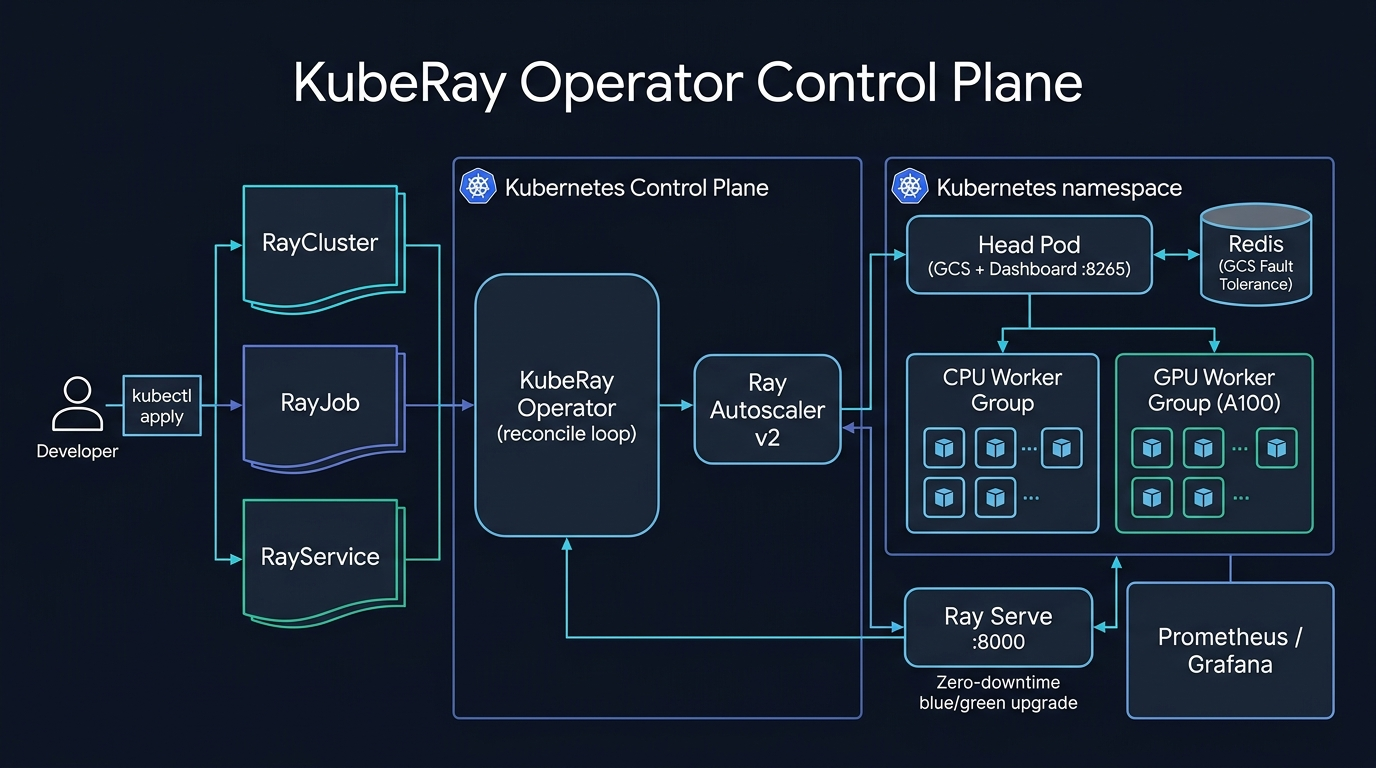
KubeRay Operator v1.3RayCluster · RayJob · RayServiceGCS Fault ToleranceAutoscaler v2Zero-Downtime Serve Upgrades
KubeRay Operator Studio
Generate production-ready KubeRay custom resources for Kubernetes: long-lived RayClusters, batch RayJobs with automatic teardown, and RayServices with zero-downtime upgrades. Includes GCS fault tolerance with external Redis, in-tree autoscaler v2, GPU worker groups and Prometheus scraping.
Worker Replicas
1 → 8
autoscaler min → max
Peak GPUs
8 × A100
nvidia.com/gpu at max scale
Head Recovery (RTO)
~30 s
GCS state restored from Redis
Idle GPU Cost Avoided
-87%
vs. static max-size cluster
⚙️ Studio Parameters Live Sync
🛡️ Production Guardrails Applied
- Head pod runs with
num-cpus: "0"so no tasks are scheduled on it - Ray image tag is pinned (no
:latest) - Ports, resource requests and limits set on every container
- RayJob sets
shutdownAfterJobFinishesand a TTL so GPUs are released - RayService uses
upgradeStrategy: NewClusterfor blue/green rollout
💰
KubeRay FinOps Impact
Scaling GPU workers from 1 to 8 on demand, and tearing RayJob clusters down when the job finishes, avoids paying for idle A100 nodes between training runs.
// Compiling KubeRay manifests...
Interactive SRE Terminal Emulator
Quick Commands:
•
•
•
$ # SRE terminal initialized. Enter command or click above.
$
📐 Architectural Execution Blueprint
Operator Reconcile Loop