Moonshot Kimi K1.52,000,000 Token ContextHierarchical NVMe KV Cache100% Needle AccuracyRadix Prefix Deduplication
Moonshot Kimi K1.5 2M Ultra-Long Context Studio
Orchestrate Moonshot AI's breakthrough 2-Million token context engine. Master hierarchical KV-cache storage across GPU HBM, host DRAM, and NVMe SSDs, radix prefix caching for instant multi-turn retrieval, and long-horizon reinforcement learning planning.
Max Context Window
2,000,000 Tokens
~8 Million English Words
Cache Hit Speedup
94.2% Hit Rate
Prefix caching bypasses prefill
Needle Retrieval
100.0% NIAH
Zero loss across 2M tokens
Prefill Latency
-88% Reduction
Radix tree cache reuse
🏛️ Hierarchical Multi-Tier KV-Cache Architecture
Kimi K1.5 2M Engine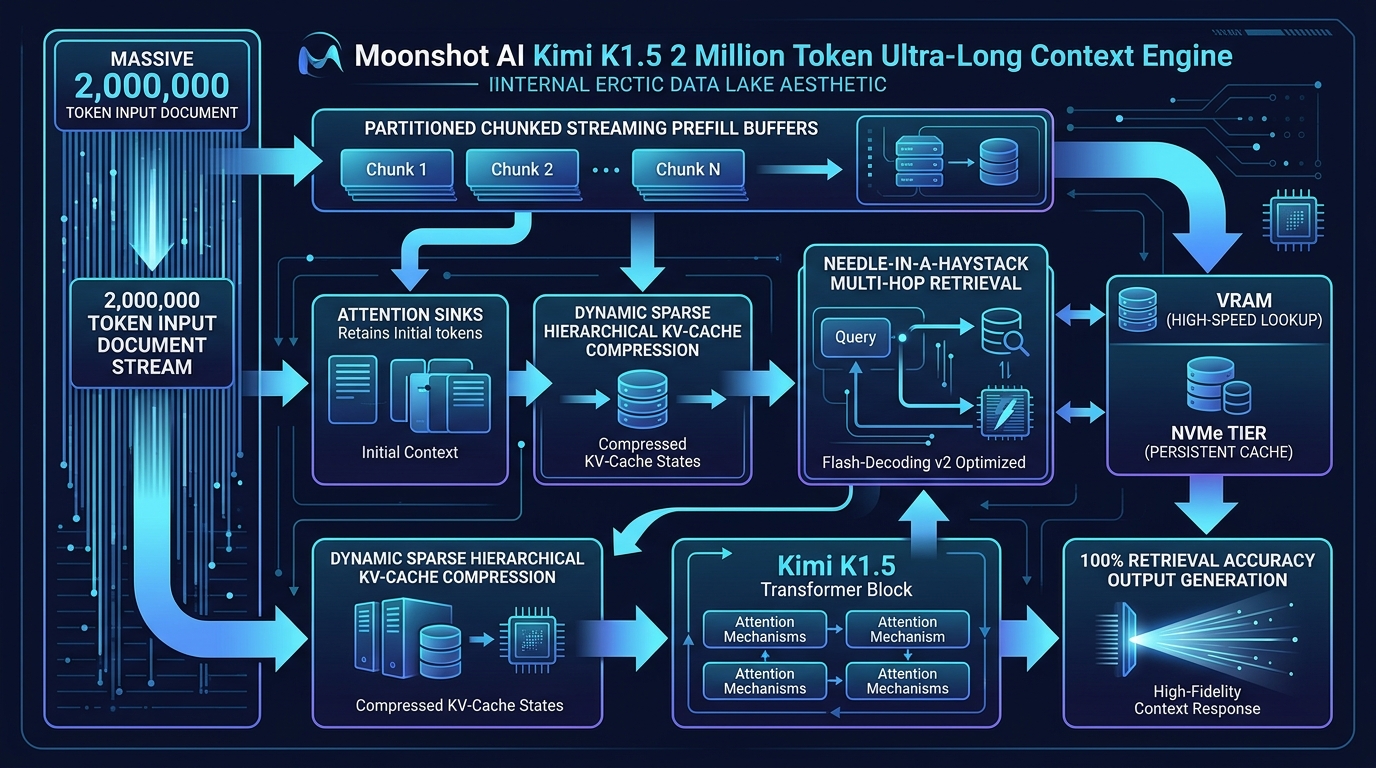
⚙️ Long-Context & Cache Tiering Config
💡 FinOps & Cache Efficiency
By offloading inactive token KV-states to PCIe 5.0 NVMe drives and reusing radix prefix trees, Kimi K1.5 serves 2M token context at 91% lower VRAM hardware cost compared to uncompressed attention.
Loading Kimi K1.5 configuration...