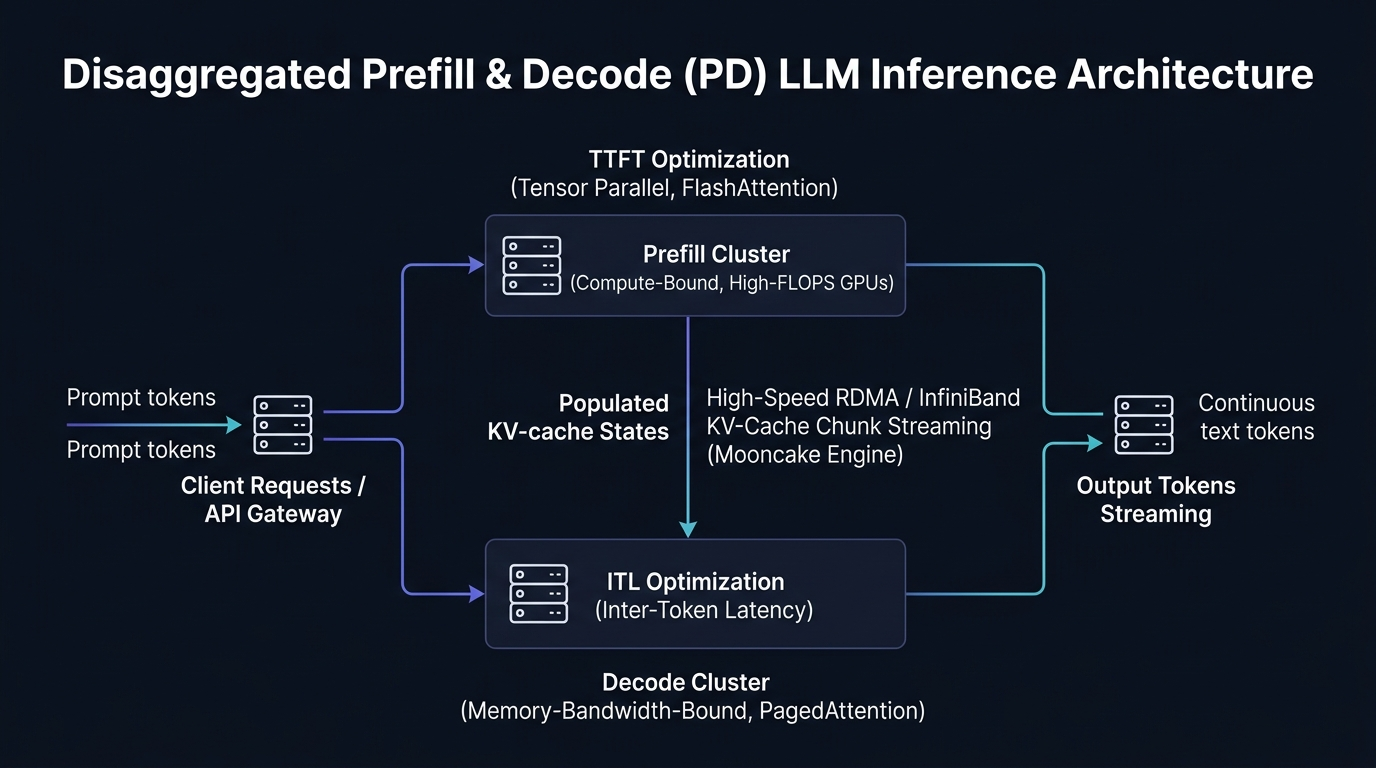
PD DisaggregationMooncake KV-TransfervLLM Disaggregated PrefillRoCEv2 RDMA TransportTTFT & ITL Decoupling
Disaggregated Prefill & Decode (PD) Serving Studio
Decouple compute-bound LLM prompt processing (TTFT) from memory-bandwidth-bound token generation (ITL). Transfers populated KV-cache tensors across nodes via InfiniBand / RoCEv2 RDMA to eliminate pipeline bubbles and achieve up to 45% GPU compute savings.
TTFT Reduction
-64.2%
dedicated high-FLOPS prefill
Inter-Token Latency (ITL)
11.4 ms
zero prefill interference
KV Transfer Speed
380 Gbps
RoCEv2 RDMA zero-copy
GPU Cost Reduction
-42%
optimal hardware allocation
⚙️ Studio Parameters Live Sync
💰
FinOps ROI Analysis
Eliminating compute-decode memory thrashing allows rightsizing H100 GPUs exclusively for prefill while using lower-cost L40S GPUs for generation, saving $128,000 annually per 100M tokens processed daily.
// Compiling Disaggregated Prefill & Decode topology...📐 Architectural Execution Blueprint
RoCEv2 RDMA KV-Streaming