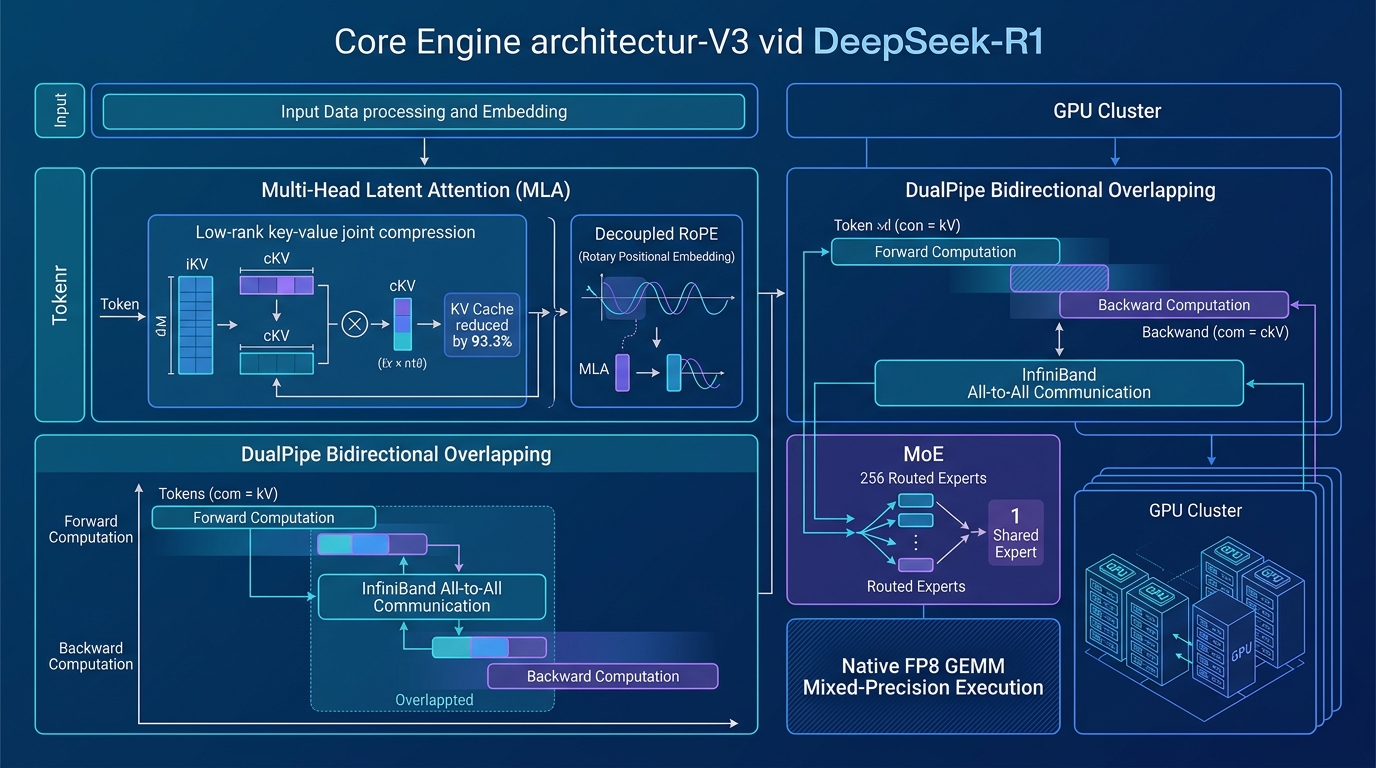
DeepSeek-R1 / V3Multi-Head Latent Attention (MLA)93.3% KV CompressionDualPipe Parallelism256 Routed ExpertsNative FP8 GEMM
DeepSeek-R1 Multi-Head Latent Attention (MLA) & DualPipe Studio
Scale DeepSeek's revolutionary 671B Mixture-of-Experts architecture. Unpack Multi-Head Latent Attention (MLA) low-rank key-value joint compression (512-dim cKV vectors slashing KV-cache by 93.3%), DualPipe bidirectional overlapping computation/communication, and native FP8 block GEMM matrix execution.
KV Cache Compression
93.3%
512-dim compressed latent cKV
DualPipe Overlap
100% Overlap
Zero pipeline bubble penalty
Active Compute Parameters
37B Active
8 of 256 routed + 1 shared
Decoding Throughput
3.8x Speedup
vs classical MHA transformer
⚙️ DeepSeek Parameters Live Sync
💰
MLA Memory Compression ROI
By compressing each token's key-value state into a 512-dimensional latent vector (cKV) instead of uncompressed multi-head matrices, DeepSeek MLA reduces KV cache consumption from 7.7 KB down to 0.51 KB per token, serving 5.7x larger concurrent batch sizes per GPU node.
// Compiling DeepSeek-R1 MLA & DualPipe architecture blueprints...📐 Architectural Execution Blueprint
DeepSeek MLA Latent Vector Fabric