ROCm 6.2AMD Instinct MI300X (192GB HBM3)vLLM ROCm EnginePyTorch FSDPTriton gfx942
AMD ROCm 6.2 & Instinct MI300X AI Training & Inference Studio
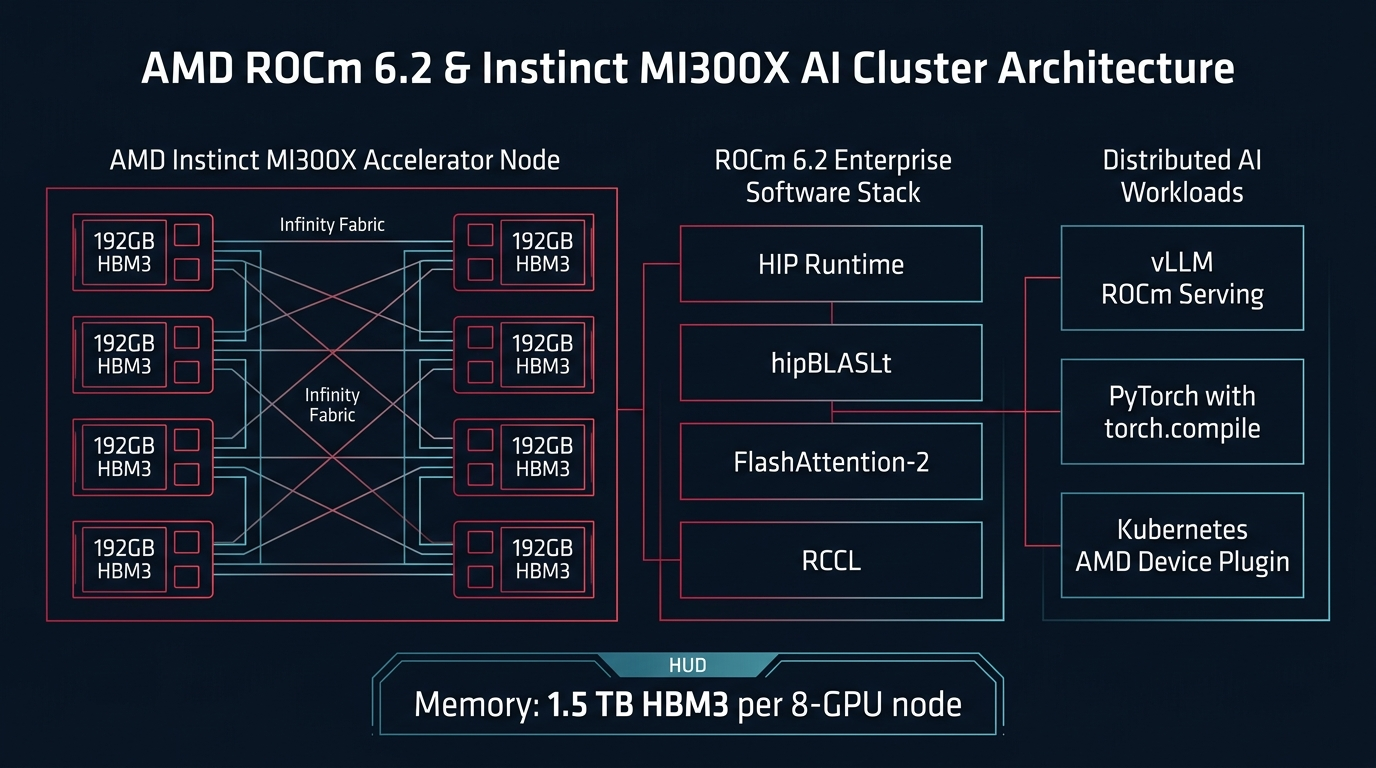
Scale open-weights LLMs (Llama-3.3 70B, DeepSeek-V2.5, Qwen2.5) on AMD Instinct™ MI300X accelerators with 192GB HBM3 memory per GPU (5.3 TB/s bandwidth). Deploy vLLM with FlashAttention-2 HIP kernels, PyTorch FSDP multi-node distributed training, and Kubernetes AMD GPU device plugins.
Memory Bandwidth
5.3 TB/s
192 GB HBM3 per accelerator
Single-Node Context
128k Tokens
1.5 TB aggregate node VRAM
Peak Compute (FP8)
1,307 TFLOPS
Matrix Core gfx942 target
TCO Reduction
-42% vs H100
Open ecosystem & higher VRAM
⚙️ MI300X Parameters Live Sync
💡
HBM3 Density Advantage
With 192GB HBM3 per GPU, a single 8-GPU MI300X server holds 1.536 TB of high-speed memory at 5.3 TB/s bandwidth, running 70B parameter models at full FP16 with 128k context without tensor-parallel sharding across multiple nodes.
// Compiling ROCm 6.2 & MI300X blueprints...📐 Architectural Execution Blueprint
AMD Instinct MI300X Fabric